 35cdcab1c5
* feat(scheduler): lifecycle rules, goal/limit parity and coded errors for scheduled tasks

- Migration 0031: nullable scheduled_tasks.unmet_streak_after_seq (internal
  streak boundary) and stop_condition (the user's stop rule, own column).
- Stop rule is normalized (stop_rule.py) and appended only at launch; the
  stored prompt never contains it. Wording adapts when scheduler.tool_enabled
  is off.
- Willem 1: page-created tasks get goal evaluation, <standing_notes>, the
  previous-run reference and own-schedule stop; request_stop and the
  scheduled capability no longer require an origin conversation.
- Repository: single reactivation choke point raising
  ScheduledTaskLimitsExhausted; streak boundary moves on goal/prompt/stop
  condition/note changes (not on resume); goal-check failures neither count
  nor reset the streak; pause of a finished task returns "finished"; trials
  on a paused task keep the host pause marker.
- New repository reads: automatic_runs_used_for, active_run_status_for,
  list_manageable_from_thread, thread_relation/thread_run on thread tasks,
  task_ids_for_thread, run_number, and run_number/total_tokens/summary on
  run history rows.
- REST: goal/max_runs/end_at/stop_condition on create and PATCH (null
  clears, naive end_at = task timezone), resume recomputes from now with an
  optional renewal body, once_time_passed, task_finished, limits_exhausted,
  scheduler_not_running on create, trigger returns outcome/existing/thread_id,
  task responses add automatic_runs_used and active_run_status.
- Coded errors {code, message, params} for routes, shared validation and the
  chat capability (scheduled_task_errors.py), pinned by
  contracts/scheduled_task_errors_contract.json; goal notes contract v2 with
  check_failure_codes, scheduled_origin_key and host_run_errors (host_notes.py).
- /api/features adds scheduled_tasks {available, running, tool_enabled,
  min_interval_seconds}; ScheduledTaskService.is_running.
- Docs: six README scheduler sections, API.md scheduled tasks section
  (breaking error shape), CONFIGURATION.md, AGENTS notes, CHANGELOGs.
- Tests: migration 0031, stop rule, error contract, run listing, lifecycle
  over HTTP, repository, service and capability cases; updated tests for the
  new error shape, finished-task pause and head revision.

* feat(scheduler): conversation update/resume, run-conversation authority and readable launches

- schedule_task: update and resume actions, stop_condition and clear_fields
  parameters, plain parameter types (value rules come back as coded results),
  rewritten docstrings for schedule_task and stop_scheduled_task.
- Capability: update/resume share the REST validation and error codes;
  interactive turns in a task's run conversation may manage that task;
  scheduled runs keep only own-stop; grants require a running scheduler.
- Results: compact JSON-safe task views with local times, display card/text,
  last run in list, timezone_source/browser_timezone, now_local; no ISO, user,
  lease or origin fields; stop_instructions removed.
- Timezone: explicit > browser (context.client_timezone, validated in
  start_run and never forwarded to the run config) > not needed for intervals
  and offset run_at > timezone_required.
- Trial gate accepts natural direct requests after acknowledgements and
  particles; trial results report thread_id and existing.
- Scheduled launches: stable message id scheduled-<task_run_id>, server-owned
  deerflow_scheduled_origin metadata with the user-language parts, run thread
  title for fresh-thread tasks.
- Worker records goal continuations in the verdict; lead prompt language rule
  covers stored task text and scheduled runs.
- Docs: six READMEs, CONFIGURATION, API, runtime/tools AGENTS, CHANGELOGs.

* feat(frontend): scheduled-task core types, formatting, errors and glossary

- throwGatewayApiError now throws GatewayApiError (status, code, params,
  rawMessage); message stays the string detail or detail.message
- scheduled-task types gain stop_condition, automatic_runs_used,
  active_run_status, origin/notes, run_number/total_tokens/summary, thread
  relation, trigger result, renewal and scheduled origin; isTaskBusy and
  hasActiveRun helpers
- api: fetchScheduledTask, resume with optional renewal body, typed trigger
  result and update payload with null clears
- hooks: polling at 3 s while a run is active (list, thread list, run
  history), useScheduledTask with live gating and final 404, useInView,
  localized error toasts; run history refreshes tasks when a run finishes
- new pure modules: errors.ts (contract code to localized copy), format.ts
  (relative task times, viewer time, display zone), status.ts, actions.ts,
  run-error.ts; describeTaskSchedule in cron.ts; goal-outcome adds unchecked
  goal checks, describeTaskOutcome and parseStopRunId
- features: scheduled_tasks block with defaults when missing
- buildRunContext sends client_timezone
- titleOfThread takes a localized untitled label; breadcrumb names scheduled
  tasks and agents; reference chips use the localized untitled label
- schedule input: shared browserTimeZone, labelled selects, aria-pressed
  type toggles, interval minimum from the hint template
- i18n: all PR1 scheduled-task keys in en-US and zh-CN, glossary fixes,
  recipe instructions moved into i18n
- e2e mocks follow the new task, trigger, resume, thread-task and features
  shapes; expectNoRawIdentifiers helpers for e2e and DOM tests
- tests for errors, format, cron, status, actions, goal outcome, run errors,
  hooks, run context, thread titles and features; scheduled e2e copy updated

* feat(frontend): list-first scheduled tasks page with outcomes and editable goals

- page.tsx is now a thin composition of components/workspace/scheduled-tasks:
  status tabs (All/Active/Paused/Finished) and search over the task list,
  ?task_id= deep link with router.replace on selection, ?thread_id= chip
  with Show all, empty state, scheduler-off notice and unavailable state
- task list rows show the schedule in words and one status line (next run,
  running now, paused by agent, auto-paused, finished by its cap)
- task detail: status badge, actions from availableActions with reasons,
  More actions menu (Duplicate, Copy task ID, Delete), outcome notice,
  Runs / Stops when / Each run's goal / Does / Notes from chat / History,
  origin chat link; success toasts for every action
- run rows: run number or Trial run, summary, goal and assumption badges,
  continuations, tokens, Open chat link; raw errors and the evaluator
  reason only behind Details
- create/edit/duplicate dialog with goal, stop condition, safety caps and
  advanced agent/context options; PATCH sends only changed fields, null
  clears a cap
- renew dialog raises or removes caps and resumes in one request; a
  limits_exhausted Resume opens it
- removed i18n keys the old page used; added feedback.resumedNoTime
- recorded en-3 and zh-1 page fixtures; scheduled e2e specs rewritten for
  the new page; DOM tests for the detail and the form dialog
- CHANGELOG entries and the frontend AGENTS.md scheduled-task note

* feat(frontend): live schedule card, run conversation provenance and header entry

- schedule_task results (create, update, pause, resume, trial, delete) become
  an assistant:scheduled-task message group rendered as a live card: schedule,
  next run, stop condition with the safety cap, goal, where results go, Run
  once now, Pause/Resume and Open task; the card polls the task only while it
  is on screen and shows deleted, scheduler-off and limits-exhausted states
- one card per task per assistant turn; the card group is not a turn boundary
  for usage, branching, editing, outline or skill attribution
- a human message with deerflow_scheduled_origin stays a human group with
  scheduledOrigin and renders as a "Scheduled run / Trial run" block with the
  task instructions, stop condition and notes collapsed; the launched text is
  never shown and the message is not editable
- readable step labels for schedule_task actions and stop_scheduled_task
- ThreadScheduledTasksButton replaces the header link: hidden without tasks,
  shows the count, links to the task (or the chat filter), and a run's chat
  links to its task
- recorded en-3 / zh-1 chat and run-thread fixtures; chat-card and run-thread
  e2e specs; unit and DOM tests for parsing, grouping, turn boundaries, card,
  run block, header button, step labels and reconnect hydration
- i18n: header.countLabelOne added, unused card.next removed; CHANGELOG and
  frontend AGENTS.md notes

* fix(scheduler): address verification findings

Move the scheduled-task lifecycle guidance from backend/AGENTS.md into the persistence guide and leave a one-line pointer, so the effective AGENTS.md chains for agents/middlewares, sandbox and subagents stay under the 98304-byte hard limit enforced by scripts/check_agent_guidance.py in lint-check.

* fix(scheduler): address review findings

* fix(gateway): no-transform on SSE responses

All four text/event-stream responses (thread run create stream, join,
existing-run GET/POST stream, stateless create stream) now take their
headers from app/gateway/sse_headers.py and send
Cache-Control: no-cache, no-transform, so compressing proxies such as
Next's rewrite proxy stop buffering streams. Content-Location and
X-Accel-Buffering are unchanged; scheduled and MCP-notification runs keep
stream_mode=None.

Tests pin the headers on every SSE route and fail on a literal no-cache
header left in routers. Docs: API.md SSE headers note, CHANGELOGs.

* feat(scheduler): per-owner run cap and fair queue selection

New scheduler.max_concurrent_runs_per_user (default 2, 0 = off, effective
min(cap, max_concurrent_runs)) caps launching/running scheduled runs per task
owner. claim_queued_run checks it right after the global count under the same
budget lock, so it is atomic across workers and Pods. list_queued_runs ranks
same-thread FIFO heads per owner with ROW_NUMBER() OVER (PARTITION BY owner)
and orders the batch by that rank, so the drain is owner-fair even with the
cap off; owners at their cap drop out before the batch limit. Orphan rows
(task deleted while queued) are never held back by the cap.

Gateway lifespan passes the startup value; the service constructor default
stays 0. Docs: config.example.yaml (config_version 54), CONFIGURATION.md,
the six READMEs, backend AGENTS.md, CHANGELOGs (behavior change flagged).
The live-task quota is untouched.

* feat(scheduler): durable lifecycle events for the originating chat

When a chat-created schedule is paused by the agent, auto-paused or finishes,
finalization now reports task_stopped / task_paused / task_finished, only on a
live -> paused/finished transition. The new finish_task_at_end_condition
replaces the three inline "mark completed" blocks (admission rejected as ended,
claim-time skip, complete_if_ended), so every site emits exactly once.

The scheduler's finalization observer is always installed. It writes
scheduled_task_events rows for the originating chat in the same transaction as
the state change, deduplicated on (task_id, anchor, event), with a title
snapshot, stop condition, run number, last run outcome and the chat's newest
run as placement anchor. Lookups fall back on bad stored data; only database
errors propagate. Manual trials drop only run_* events. The IM step keeps
PR1's selection until B4.

New GET /api/threads/{thread_id}/scheduled-task-events (owner check, caller's
rows, oldest first); rows survive task deletion and go with the chat.
Migration 0032_activity_and_task_events adds the events table plus the
run-origin column/index and read-state tables used later, each object guarded
on its own. Contract scheduled_goal_notes v3 pins the lifecycle vocabulary.
Docs: API.md, migrations chain, backend AGENTS.md, six READMEs, CHANGELOGs.

* feat(scheduler): honest, localized and self-contained IM notices

Every scheduled-task IM notice is now enqueued by the finalization observer
in the transaction that records the outcome, one message per occurrence
(task_stopped > task_paused > task_finished > run_failed > run_unmet >
run_completed; a once task sends only its run event). The merged auto-pause
replaces the separate unmet + pause messages, agent stops and finishes now
notify, and recovery-finalized runs notify exactly once. Idle finishes use a
deterministic idle: key derived from the lifecycle anchor. The old
non-transactional enqueue in handle_run_completion is removed.

New app/channels/capabilities.py holds CHANNEL_CAPABILITIES with a
proactive_notifications flag (adds the missing qq entry); only push-capable
providers (WeCom) get rows, /api/channels/providers returns the flag, and the
worker ends legacy rows for other providers as terminal failed.

New app/scheduler/notification_text.py renders en-US/zh-CN text: title, what
happened (plus the last run's outcome), the tasks page's one-line run summary
(redacted) when the agent replied, and a closing line. No IDs, no links, no
public_base_url. Locale is the owner's new `locale` preference, else the new
channel_connections.notification_locale (default en-US).

Docs: config.example.yaml (config_version 55), CONFIGURATION.md, API.md,
channels AGENTS.md, six READMEs, CHANGELOGs (behavior change flagged).

* feat(gateway): thread origin, activity feed and read markers for server-created threads

Runs started by the server for a user (scheduler, IM channels, GitHub
agents, extension handles, MCP notifications) now carry a server-owned
metadata.deerflow_origin {kind, provider?, namespace?} (new harness module
deerflow.runtime.run_origin, pinned by contracts/thread_origin_contract.json).
It is stamped only from request.state.run_origin or by the internal channel
caller; run admission drops client copies from both metadata and
config.metadata, and thread create/patch strip it. RunRepository derives
runs.origin_kind on put and on create_thread_operation_atomic (agent runs
only), and gains latest_change().

New ThreadReadRepository keeps a per-user, never-decreasing read position
(thread_read_markers) and a per-user read clock (thread_read_versions).
POST /api/threads/{id}/read marks a thread read, thread search items carry
unread, and thread delete removes the markers. GET /api/thread-activity pages
the caller's run changes over the run-change clock, returns only threads
changed by server-originated runs plus read_version, and 503s without SQL;
/api/features reports thread_activity.available.

Docs: API.md, gateway AGENTS.md (condensed to stay under its budget),
CHANGELOGs.

* fix(scheduler): adapt PR2 to PR1 follow-ups

PR1 moved the scheduled-task lifecycle rules out of backend/AGENTS.md into
the persistence guide and grew the sandbox AGENTS.md chain to within 267
bytes of its hard limit. The per-owner queue-fairness detail now lives in
the persistence guide next to the lifecycle rules (backend/AGENTS.md keeps
the cap and a link), so check_agent_guidance passes again.

PR1's goal-outcome unit test pinned scheduled_goal_notes_contract version 2;
PR2 bumps it to 3 (lifecycle vocabulary only, the v2 keys are unchanged).

* fix(scheduled-tasks): polish from live acceptance

- zh schedule wording: an interval of one unit reads 每分钟 / 每小时 / 每秒,
  and a saved interval of whole days reads 每天 / 每 2 天 (Every day / Every 2
  days) instead of 每 1 分钟 or 每 24 小时; several units keep the number
- zh spacing: 已于{time} 满足 and 在{time} 的运行中 now leave a space between
  the interpolated time and the Chinese after it; a copy test guards every
  scheduled-task zh string against a placeholder glued to Chinese
- run summary: when the first line of the final reply only leads in to a list
  (ends with ":" or ":"), the list items follow it as plain text (bullets,
  numbering, checkboxes, bold, code and links stripped), joined with ";" for
  CJK text and "; " otherwise, within the 160-character cap
- a schedule_task result (create, update, pause, resume, trial, delete) that
  arrives in a chat invalidates that chat's task list, the tasks list and the
  named task, so the header button and cards update without waiting for the
  idle poll; results already in the loaded history do not refetch
- e2e and unit fixtures are now the live acceptance recordings (DeepSeek
  Flash, demo data, fictional names): live-weekday.json (create, trial, edit,
  pause, resume in one zh chat) and live-minute.json (per-minute chat, run 1
  and run 2, paused by the agent), fetched with GET from the demo Gateway and
  trimmed; the hand-shaped en-3 / zh-1 fixtures are removed and the chat-card,
  run-thread and tasks-page specs run in both locales over the recorded data

* docs(changelog): reference #6378 for the scheduled-tasks entries

* docs(agents): shorten the scheduled-task pointer to stay under the guidance limit

* test(scheduled-tasks): pin the live takes to their recorded time zone

The live fixtures were recorded in Asia/Shanghai, and an interval task
reads in the viewer's zone, so the 16:48 assertions failed on UTC CI
runners. Pin the browser zone in the two live-take e2e specs and the
zh live-take unit test.

* feat(frontend): thread origin, activity polling, read markers and task events core

Frontend core for server-created threads and schedule lifecycle events
(PR2 F1); the sidebar markers (F2) and the chat event line (F3) build on it.

- core/threads/origin.ts: threadOriginOf reads metadata.deerflow_origin,
  then channel_source (github -> GitHub origin), then a legacy
  scheduled_task_id; key and kinds pinned to
  contracts/thread_origin_contract.json. labelOfThreadOrigin and the now
  exported labelOfChannelProvider(provider, t) use the new localized
  threads.origin.providers names (飞书, 企业微信, ...), with the English map
  (gaining GitHub) only as the fallback.
- core/threads/activity.ts: useThreadActivity polls /api/thread-activity
  every 15 s (focus refetch, never in the background, off unless
  features.thread_activity.available). The first response only seeds the
  cursor; server-origin threads, a truncated page or a higher read_version
  invalidate the thread lists, a scheduled thread also ["scheduled-tasks"];
  an invalid cursor re-seeds. useMarkThreadRead debounces POST /read by 1 s,
  skips a thread whose cached unread is false, patches the search and
  infinite caches optimistically and stores the returned read_version so a
  tab's own read does not refetch its lists. AgentThread gains unread.
- core/scheduled-tasks/events.ts: ScheduledTaskEvent, the events query
  (["scheduled-tasks","thread-events",id], one fetch per saved chat, not
  gated on the task list so a deleted task's lines stay, refetched when a
  task of the chat changes status or finishes a run), describeTaskEvent
  (en/zh copy, title and condition as segments, last-run suffix, See that
  run / Open task) and placeTaskEvents (end of the after_run_id turn, else
  the tail, ordered by created_at); lifecycle names pinned to contract v3.
- features: thread_activity (default unavailable); channels:
  proactive_notifications on providers.
- Locale sync: the I18nProvider reports the UI language and a signed-in
  preference session saves it as the new `locale` preference when the
  account's differs (and on every switch), so IM notices follow the UI
  language; nothing is written with auth disabled.
- i18n: threads.* (unread, origin labels, provider names),
  scheduledTasks.events.*, history.waitingForSlot (now shown for queued run
  rows), channels.scheduledUpdates.*.
- e2e mocks: thread activity feed and controller, POST /read, the events
  route, providers with proactive_notifications, search unread, features
  thread_activity (off by default). Preference e2e mocks return the UI
  locale so they keep asserting only their own edits.
- Docs: frontend AGENTS.md, CHANGELOGs.

* fix(scheduled-tasks): keep untouched end times and drop a chat filter the new task is not in

- The edit, duplicate and renew dialogs keep a stored end time's instant
  while its field still shows it. A minute-precision wall value cannot
  keep seconds or name the later 01:30 of a DST fall-back, so a
  title-only edit moved the cap an hour earlier, and raising the run
  limit re-sent the end time without its seconds.
- Creating or duplicating a task from a chat's task view drops the chat
  filter when the new task does not belong to that chat, instead of
  showing "This task isn't one of this chat's tasks".

* feat(frontend): origin markers and unread state in the thread lists

Server-created threads (PR2 F2) now say who created them and whether they
are new, in the sidebar and on the Chats page, and reach an open sidebar
without a reload.

- ThreadOriginIcon (thread-channel-source.tsx): clock for a scheduled run,
  the provider mark for IM threads, the GitHub mark (new in
  ChannelProviderIcon) for GitHub threads, a puzzle piece for extensions;
  the localized "Scheduled run" / "From Feishu" / "From GitHub" / "From an
  extension" label is its accessible name and tooltip. ThreadChannelIcon
  stays exported as a wrapper, and the provider chip tooltip is localized
  (no more "Feishu channel").
- Unread dot after the title (aria-hidden dot plus sr-only "Unread"); the
  row aria-label becomes "{title}, unread" / "{title},未读". Never shown for
  the open thread.
- WorkspaceSidebar mounts useThreadActivity once.
- useMarkOpenThreadRead (components/workspace/chats): the default and
  custom-agent chat pages mark the thread read once its metadata has
  loaded, when its cached unread flips to true while open, when the tab
  becomes visible, and from onFinish (a send or a joined run ended). Each
  trigger goes through useMarkThreadRead, so it is debounced and a no-op
  while the cached unread is false.
- Tests: thread-origin-icon and recent-chat-list DOM tests (en/zh, active
  row, no raw identifiers), use-mark-open-thread-read DOM tests,
  e2e thread-activity.spec.ts (new scheduled run appears unread within one
  fake-clock poll without a reload, opening it posts /read and clears the
  dot, a read on another device clears it, IM and GitHub markers, zh
  labels, the Chats page, no polling when unavailable);
  thread-history.spec.ts now finds the localized origin icon.
- Docs: frontend AGENTS.md, CHANGELOGs.

* feat(frontend): schedule event line in the originating chat and channel notice support

The chat that created a schedule now says when the schedule paused or
ended, and the channel cards say which apps receive scheduled task updates
(PR2 F3).

- ScheduledTaskEventLine (mockup m2, marker 4): a dashed, muted row with
  the describeTaskEvent text (title in <strong>, stop condition clamped to
  one line with the full text in its tooltip, last-run suffix), the time
  via formatTaskTime and a right-aligned "See that run" (run chat) or
  "Open task" link. PauseCircle for paused, CircleCheck for finished and
  once-done, CircleX for once-failed. role="note", aria-label "Scheduled
  task update" / "定时任务通知", data-task-id and data-event-id only.
- MessageList takes scheduledTaskEvents and renders placeTaskEvents output
  through a new VirtualMessageList.renderAfterGroup, so each line sits at
  the end of its after_run_id turn inside the group's measured row (also
  when the list virtualizes); lines with nowhere to go render at the tail.
- Both chat pages load useThreadScheduledTaskEvents (not gated on the task
  list, so the lines stay after a task is deleted). The custom-agent page
  passes its agent so "See that run" opens the run on that agent's route.
- ChannelScheduledUpdates: "Scheduled task updates: sent here" / "... not
  available for this app yet" (定时任务通知:会发送到这里 / 此应用暂不支持)
  on the Settings provider cards and under each sidebar channel row; nothing
  when an older backend does not report proactive_notifications.
- e2e mock controller: setScheduledTasks.
- Tests: scheduled-task-event-line and channel-scheduled-updates DOM tests
  (every kind in en and zh, hrefs, clamp, no raw identifiers, Chinese
  title), MessageList placement DOM tests; e2e
  scheduled-task-chat-events.spec.ts (the line appears with the card's
  "Paused by agent" without a reload, See that run opens the run chat,
  anchored vs tail placement, two events in time order, the line survives
  task deletion and Open task shows the task is gone; en-3 and zh-1) and
  channels.spec.ts (WeCom sent here, Feishu not yet; en and zh).
- Docs: frontend AGENTS.md, CHANGELOGs.

* fix(scheduled-tasks): tie pause notices to the pause they describe

- Paused by agent links and times only the run named in last_error. When
  that run is not loaded, the notice shows no link and the task's own time
  instead of an earlier run that also asked to stop.
- The outcome notice reads the latest history page whichever page is
  shown, so browsing older runs no longer swaps the auto-pause reason and
  "Open latest run" to an earlier miss. It shares that page's request.

* fix(scheduler): address PR2 review findings

- Event lines: hold an event whose anchor run is on an unloaded history
  page instead of placing it at the bottom (hasMoreHistory); tail fallback
  only for fully loaded (branched/pruned) history or no anchor.
- Idle-finish anchor follows its reason: end:<iso> only for an end_at
  finish, seq:<n> otherwise, so a later end-time finish is not deduplicated
  away by an earlier max_runs finish.
- Observer takes FOR SHARE on the originating threads_meta row, so a racing
  thread delete cannot leave an orphan event line.
- One taskPagePath (core), re-exported by the card.
- Notification locales derived from NotificationLocale; /preferences uses it.
- IM notices drop generic reasons (goal_not_met_yet, unknown) instead of
  repeating the sentence.
- Localized provider names on Settings cards, sidebar rows and setup dialog.
- zh event lines: no space after a Chinese title (Latin-aware gap).
- Unread row label keeps the origin marker; chats page keeps the time as a
  description.
- Sidebar shows the scheduled-updates line only for connected apps;
  Settings says "available after you connect" for unconnected push apps.
- Event line keeps a real space before the time.

* fix(scheduled-tasks): three lifecycle gaps found while re-checking review classes

- The edit form compares a cron in the form its schedule input emits, so an
  untouched "0 09 * * 0,6" is not re-sent as "0 9 * * 6,0" and a title-only
  edit no longer re-arms or refuses a finished task.
- Chat resume asks for a timezone, as update does, when a naive end_at would
  land in the UTC placeholder of a zone-free task.
- Re-arming a task clears a host pause marker, as resume does, so a later
  manual pause no longer reads as "Paused by agent".

* test(scheduler): consolidate PR2 backend test setup

- Fold the repeated task, origin-chat and observer setup of the
  lifecycle-event repository tests into one lifecycle_task builder.
- Build the per-owner-cap services through one _capped_service builder
  that keeps every cap explicit at the call site.
- Table the five SSE route header checks into one parametrized test with
  the same routes, bodies and Content-Location expectations.
- Reuse bind_wecom and hoist repeated local imports in the event tests.

Every case and assertion is kept; collected cases are unchanged.

* test(frontend): consolidate PR2 thread activity and origin test setup

Extract shared builders and helpers in the frontend tests PR2 adds, with
every case, input and assertion kept:

- activity.test.ts: seededClient/apply helpers and one LIST_KEYS constant
  replace the per-test seed, spy and apply boilerplate.
- mark-read.dom.test.tsx: newClient() and advance() replace the repeated
  QueryClient wrapper and fake-timer act blocks.
- origin.test.ts: the English and Chinese label checks become tables; the
  no-English-name check now runs on every Chinese row.
- thread-activity.spec.ts: a scheduledRun() builder replaces four inline
  copies of the scheduled run thread.
- channels.spec.ts: the PR2 block uses setLocaleCookie and one card helper.

Collected cases are unchanged (unit 211, e2e 60); no test was removed.

* fix(scheduled-tasks): keep the notice's latest-runs query from refreshing older pages

useLatestScheduledTaskRuns kept React Query's default refetch on mount,
focus and reconnect, so going offline and back while an older history page
was shown fetched the latest page again. Refreshing stays with the history,
which refreshes the latest page only while it is shown.

* fix(scheduler): two gaps found in live acceptance

- A fresh scheduled run thread is named when it launches. The worker
  copied the title to the thread list only when the run ended, so the
  sidebar, which now shows the new run thread at once, listed it as
  untitled while it ran.
- A task capped at one run finishes with "its one run is done" /
  "唯一一次运行已完成" in the chat event line and the IM notice, instead
  of "all 1 runs are done".

* test(scheduled-tasks): let the viewer's time carry its own day label

Between 16:00 and 24:00 UTC, UTC and Asia/Shanghai are on different days,
so the run prompt shows "Tomorrow 01:00 · Today 09:00 your time" and the
fixed "01:00 · 09:00 your time" assertion failed depending on the hour.

* test(scheduler): expect the one-run finish copy in service notices

* fix(gateway): create a scheduled run thread with its title

Pre-setting the name after start_run raced the thread row, which the run
worker creates asynchronously: live, one of two run threads still reached
the sidebar untitled. Run admission now creates a new thread with the title
its run input carries, which the worker would copy only at run end.

* docs(changelog): reference #6393 for the scheduled-task signal entries

* fix(scheduled-tasks): route event-line run links by the agent that ran them

The originating chat's agent was used for "See that run", but a task's
agent can change after the chat created it, so the link could open the run
chat on another agent's route. Lifecycle events now record run_agent_name,
the task's agent when the run finished (edits are refused while a run is
active), and the line routes by it.

* fix(scheduled-tasks): load up to the route's maximum of chat event lines

The chat loads its lifecycle events once, and the route's default of 50
would silently drop the oldest lines of a chat with many schedules. Ask
for the maximum, 200.

* fix(threads): keep activity reads and the first cursor in step with the lists

- Accepting the first activity cursor refreshes the thread lists once. The
  lists load on their own, possibly before a run the seed already counts,
  and later polls start after it, so such a thread never appeared.
- A local read whose returned read clock jumps past that one read also
  covers reads on other devices; the lists are refreshed instead of the
  clock silently skipping those threads' stale unread dots.
- An invalid cursor re-seeds through the same path, so it refreshes once.

* docs(agents): bring the middlewares guidance chain back under the hard limit

#6378 and #6363 each fit the budget, but together the middlewares AGENTS.md
chain on main is 98,425 bytes, 121 over the 98,304 hard limit, so Lint
Check fails on main. Move the scheduled-task recovery, launch-update and
queue-timeout rules from backend/AGENTS.md into the persistence guide's
lifecycle section, which backend/AGENTS.md already points to. The chain is
now 98,067 bytes.

* fix(helm): bump the chart's config_version to 55

config.example.yaml moved to 55 in this PR, so the Helm chart's
validate-chart drift check failed. The chart's embedded config needs no
field changes: the new scheduler and channel keys have defaults.

---------

Co-authored-by: Totoro-qaq <279883115+Totoro-qaq@users.noreply.github.com>
Co-authored-by: Willem Jiang <willem.jiang@gmail.com>
66 KiB
🦌 DeerFlow - 2.0
English | 中文 | 日本語 | Français | Русский | Português

2026年2月28日、バージョン2のリリースに伴い、DeerFlowはGitHub Trendingで🏆 第1位を獲得しました。素晴らしいコミュニティの皆さん、ありがとうございます!💪🔥
DeerFlow(Deep Exploration and Efficient Research Flow)は、サブエージェント、メモリ、サンドボックスを統合し、拡張可能なスキルによってあらゆるタスクを実行できるオープンソースのスーパーエージェントハーネスです。
https://github.com/user-attachments/assets/a8bcadc4-e040-4cf2-8fda-dd768b999c18
Note
DeerFlow 2.0はゼロからの完全な書き直しです。 v1とコードを共有していません。オリジナルのDeep Researchフレームワークをお探しの場合は、
1.xブランチで引き続きメンテナンスされています。現在の開発は2.0に移行しています。
公式ウェブサイト
実際のデモは公式ウェブサイトでご覧いただけます。
姉妹プロジェクト
- LLM Space - DeerFlow の秘密兵器をご紹介 — agent のアイデアをプロトタイピングし、ハーネスの各ステップを検査し、失敗を再生し、パフォーマンスをベンチマークするためのデスクトップツールです。
ByteDance Volcengine のコーディングプラン
- DeerFlowの実行には、Doubao-Seed-2.0-Code、DeepSeek v3.2、Kimi 2.5の使用を強く推奨します
- 詳細はこちら
- 中国大陸の開発者はこちらをクリック
InfoQuest
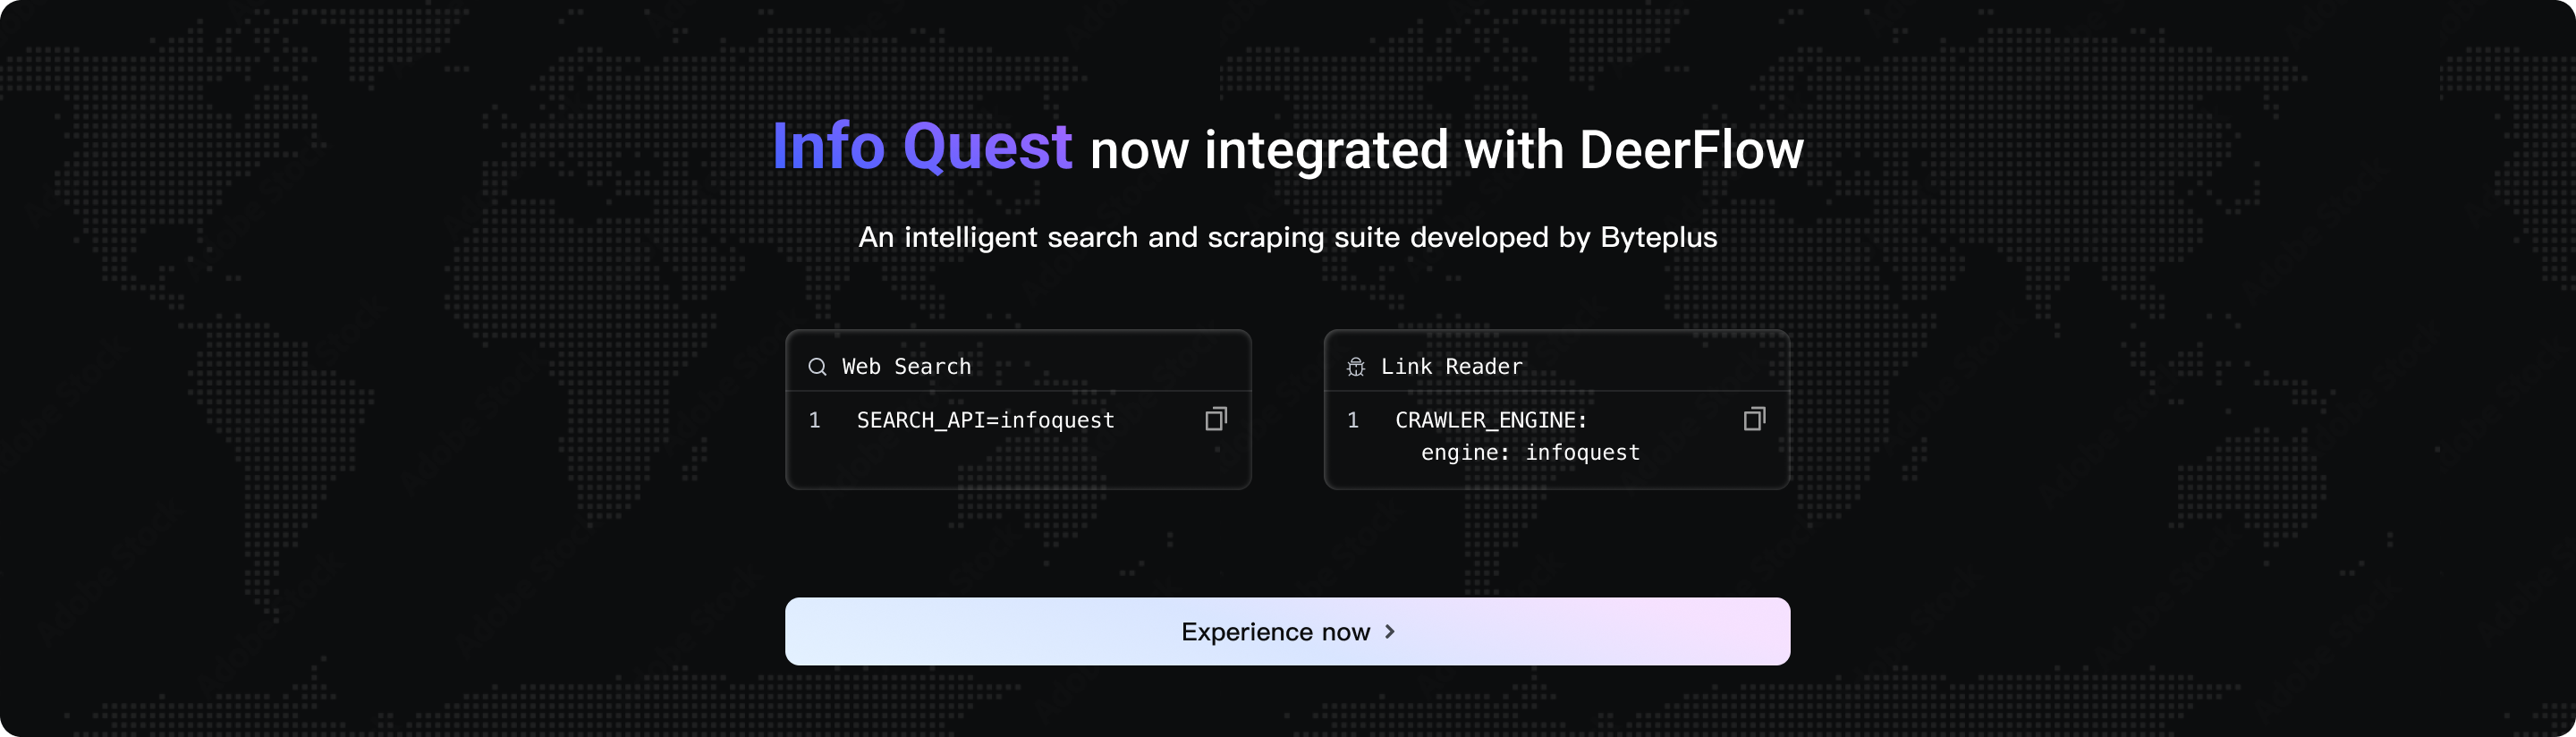
DeerFlowは、BytePlusが独自に開発したインテリジェント検索・クローリングツールセット「InfoQuest(無料オンライン体験対応)」を新たに統合しました。
目次
- 🦌 DeerFlow - 2.0
Coding Agent に一文でセットアップを依頼
Claude Code、Codex、Cursor、Windsurf などの coding agent を使っているなら、次の一文をそのまま渡せます。
DeerFlow がまだ clone されていなければ先に clone してから、https://raw.githubusercontent.com/bytedance/deer-flow/main/Install.md に従ってローカル開発環境を初期化してください
このプロンプトは coding agent 向けです。必要なら先にリポジトリを clone し、Docker が使える場合は Docker を優先して初期セットアップを行い、最後に次の起動コマンドと不足している設定項目だけを返します。
クイックスタート
設定
-
DeerFlowリポジトリをクローン
git clone https://github.com/bytedance/deer-flow.git cd deer-flow -
セットアップウィザードの実行(推奨)
プロジェクトルートディレクトリ(
deer-flow/)から以下を実行します:make setup対話式ウィザードが起動し、LLMプロバイダーの選択、オプションのWeb検索、そしてサンドボックスモード・bash権限・ファイル書き込みツールなどの実行/安全設定を順に案内します。最小構成の
config.yamlを生成し、APIキーを.envに書き込みます。所要時間は約2分です。いつでも
make doctorを実行して、設定を確認し、具体的な修正ヒントを得られます。 ローカルセットアップや実行時の問題についてGitHub issueを起票する場合は、make support-bundleを実行してください。このコマンドは報告者向けの次のステップを表示し、issueに貼り付けるための*-issue-summary.mdファイルと、AI支援でissueを起票するための*-issue-draft.mdファイルを書き出し、オプションで証跡zipを.deer-flow/support-bundles/以下に作成します。AIアシスタントがissueを起票する場合は、ドラフトを起点にして、不足している事実を創作するのではなく、すべてのREQUIREDプレースホルダーを置き換えてください。zipは、メンテナーから求められた場合、またはサマリーだけでは不十分な場合にのみ添付してください。メンテナーやAIトリアージツールはtriage.jsonから確認を始められます。バンドルに含まれるのはリダクト済みの診断情報とファイルマニフェストのみで、.env、生の会話メッセージ、ユーザーファイルの内容は含まれません。上級者向け / 手動設定:
config.yamlを直接編集したい場合は、代わりにmake configを実行して完全なテンプレートをコピーしてください。CLI連携プロバイダー(Codex CLI、Claude Code OAuth)、OpenRouter、Responses APIなどを含む完全なリファレンスはconfig.example.yamlを参照してください。手動モデル設定の例
models:
  - name: gpt-4o
    display_name: GPT-4o
    use: langchain_openai:ChatOpenAI
    model: gpt-4o
    api_key: $OPENAI_API_KEY

  - name: openrouter-gemini-2.5-flash
    display_name: Gemini 2.5 Flash (OpenRouter)
    use: langchain_openai:ChatOpenAI
    model: google/gemini-2.5-flash-preview
    api_key: $OPENROUTER_API_KEY
    base_url: https://openrouter.ai/api/v1

  - name: gpt-5-responses
    display_name: GPT-5 (Responses API)
    use: langchain_openai:ChatOpenAI
    model: gpt-5
    api_key: $OPENAI_API_KEY
    use_responses_api: true
    output_version: responses/v1

  - name: qwen3-32b-vllm
    display_name: Qwen3 32B (vLLM)
    use: deerflow.models.vllm_provider:VllmChatModel
    model: Qwen/Qwen3-32B
    api_key: $VLLM_API_KEY
    base_url: http://localhost:8000/v1
    supports_thinking: true
    when_thinking_enabled:
      extra_body:
        chat_template_kwargs:
          enable_thinking: true
OpenRouterやOpenAI互換のゲートウェイは、
langchain_openai:ChatOpenAIとbase_urlで設定します。プロバイダー固有の環境変数名を使用したい場合は、api_keyでその変数を明示的に指定してください(例:api_key: $OPENROUTER_API_KEY)。OpenAIモデルを
/v1/responses経由でルーティングするには、引き続きlangchain_openai:ChatOpenAIを使用し、use_responses_api: trueとoutput_version: responses/v1を設定してください。vLLM 0.19.0では
deerflow.models.vllm_provider:VllmChatModelを使用してください。Qwen系のreasoningモデルでは、DeerFlowはextra_body.chat_template_kwargs.enable_thinkingでreasoningを切り替え、マルチターンのツールコール会話にわたってvLLM独自の非標準reasoningフィールドを保持します。従来のthinking設定は後方互換性のため自動的に正規化されます。reasoningモデルはサーバー側で--reasoning-parser ...を付けて起動する必要がある場合もあります。ローカルのvLLMデプロイメントが空でない任意のAPIキーを受け付ける場合でも、VLLM_API_KEYにはプレースホルダー値を設定しておけます。CLI連携プロバイダーの例:
models: - name: gpt-5.4 display_name: GPT-5.4 (Codex CLI) use: deerflow.models.openai_codex_provider:CodexChatModel model: gpt-5.4 supports_thinking: true supports_reasoning_effort: true - name: claude-sonnet-4.6 display_name: Claude Sonnet 4.6 (Claude Code OAuth) use: deerflow.models.claude_provider:ClaudeChatModel model: claude-sonnet-4-6 max_tokens: 4096 supports_thinking: true- Codex CLIは
~/.codex/auth.jsonを読み取ります - Claude Codeは
CLAUDE_CODE_OAUTH_TOKEN、ANTHROPIC_AUTH_TOKEN、CLAUDE_CODE_CREDENTIALS_PATH、または~/.claude/.credentials.jsonを受け付けます - ACPエージェントのエントリはモデルプロバイダーとは別物です。
acp_agents.codexを設定する場合は、npx -y @zed-industries/codex-acpのようなCodex ACPアダプターを指定してください - macOSでは、必要に応じてClaude Codeの認証情報を明示的にエクスポートしてください:
eval "$(python3 scripts/export_claude_code_oauth.py --print-export)"APIキーは
.envで手動設定する(推奨)ことも、シェルでエクスポートすることもできます:OPENAI_API_KEY=your-openai-api-key TAVILY_API_KEY=your-tavily-api-key - Codex CLIは
アプリケーションの実行
オプション1: Docker(推奨)
開発環境(ホットリロード、ソースマウント):
make docker-init    # サンドボックスイメージをプル(初回またはイメージ更新時のみ)
make docker-start   # サービスを開始(config.yamlからサンドボックスモードを自動検出)
make docker-startは、config.yamlがプロビジョナーモード(sandbox.use: deerflow.community.aio_sandbox:AioSandboxProviderとprovisioner_url)を使用している場合にのみprovisionerを起動します。
本番環境(ローカルでイメージをビルドし、ランタイム設定とデータをマウント):
make up     # イメージをビルドして全本番サービスを開始
make down   # コンテナを停止して削除
Note
Agentランタイムは現在Gateway内で実行されます。
/api/langgraph/*はnginxによってGatewayのLangGraph-compatible APIへ書き換えられます。
アクセス: http://localhost:2026
詳細なDocker開発ガイドはCONTRIBUTING.mdをご覧ください。
オプション2: ローカル開発
サービスをローカルで実行する場合:
前提条件:上記の「設定」手順を先に完了してください(make setup)。make devにはプロジェクトルートに有効なconfig.yamlが必要です。DEER_FLOW_PROJECT_ROOTでプロジェクトルートを明示的に指定するか、DEER_FLOW_CONFIG_PATHで特定の設定ファイルを指定できます。実行時の状態はデフォルトでプロジェクトルート直下の.deer-flowに書き込まれ、DEER_FLOW_HOMEで移動できます。skillsはデフォルトでプロジェクトルート直下のskills/から読み込まれ、DEER_FLOW_SKILLS_PATHで移動できます。起動前にmake doctorを実行して設定を確認してください。
Windowsでは、ローカル開発フローはGit Bashから実行してください。bashベースのサービススクリプトはネイティブのcmd.exeやPowerShellではサポートされておらず、一部のスクリプトがGit for Windowsのcygpathなどのユーティリティに依存しているため、WSLでの動作も保証されません。
-
前提条件の確認:
make check # Node.js 22+、pnpm、uv、nginxを検証 -
依存関係のインストール:
make install # バックエンド+フロントエンドの依存関係をインストール -
(オプション)サンドボックスイメージの事前プル:
# Docker/コンテナベースのサンドボックス使用時に推奨 make setup-sandbox -
サービスの開始:
make dev -
アクセス: http://localhost:2026
詳細設定
サンドボックスモード
DeerFlowは複数のサンドボックス実行モードをサポートしています:
- ローカル実行(ホストマシン上で直接サンドボックスコードを実行)
- Docker実行(分離されたDockerコンテナ内でサンドボックスコードを実行)
- KubernetesによるDocker実行(プロビジョナーサービス経由でKubernetesポッドでサンドボックスコードを実行)
Docker開発では、サービスの起動はconfig.yamlのサンドボックスモードに従います。ローカル/Dockerモードではprovisionerは起動されません。
お好みのモードの設定についてはサンドボックス設定ガイドをご覧ください。
MCPサーバー
DeerFlowは、機能を拡張するための設定可能なMCPサーバーとスキルをサポートしています。
HTTP/SSE MCPサーバーでは、OAuthトークンフロー(client_credentials、refresh_token)がサポートされています。
詳細な手順はMCPサーバーガイドをご覧ください。
IMチャネル
DeerFlowはメッセージングアプリからのタスク受信をサポートしています。チャネルは設定時に自動的に開始されます。いずれもパブリックIPは不要です。
DeerFlowはワークスペースUIでユーザー所有のIMチャネル接続を公開することもできます。channel_connectionsを有効にすると、ログイン済みユーザーはサイドバー / Settings > ChannelsからTelegram、Slack、Discord、Feishu/Lark、DingTalk、WeChat、WeCom、QQ、Buzzをバインドできます。これは既存のchannels.*送信トランスポートを再利用するため、パブリックIPやプロバイダーのコールバックURLは不要です。受信したIMメッセージは接続したDeerFlowユーザーアカウントの下で実行されます。セットアップとセキュリティ上の注意はIM Channel Connectionsをご覧ください。
| チャネル | トランスポート | 難易度 |
|---|---|---|
| Telegram | Bot API(ロングポーリング) | 簡単 |
| Slack | Socket Mode | 中程度 |
| Feishu / Lark | WebSocket | 中程度 |
| Tencent iLink(ロングポーリング) | 中程度 | |
| WeCom | WebSocket | 中程度 |
| DingTalk | Stream Push(WebSocket) | 中程度 |
| WebSocket(テキストのみ:個別チャットとグループ @) | 中程度 | |
| Buzz | Nostr relay(WebSocket、NIP-42) | 中程度 |
config.yamlでの設定:
channels:
  # LangGraph-compatible Gateway API base URL(デフォルト: http://localhost:8001/api)
  langgraph_url: http://localhost:8001/api
  # Gateway API URL(デフォルト: http://localhost:8001)
  gateway_url: http://localhost:8001

  # オプション: 全モバイルチャネルのグローバルセッションデフォルト
  session:
    assistant_id: lead_agent
    config:
      recursion_limit: 100
    context:
      thinking_enabled: true
      is_plan_mode: false
      subagent_enabled: false

  feishu:
    enabled: true
    app_id: $FEISHU_APP_ID
    app_secret: $FEISHU_APP_SECRET
    # domain: https://open.feishu.cn       # China (default)
    # domain: https://open.larksuite.com   # International

  wecom:
    enabled: true
    bot_id: $WECOM_BOT_ID
    bot_secret: $WECOM_BOT_SECRET

  slack:
    enabled: true
    bot_token: $SLACK_BOT_TOKEN     # xoxb-...
    app_token: $SLACK_APP_TOKEN     # xapp-...(Socket Mode)
    allowed_users: []               # 空 = 全員許可

  telegram:
    enabled: true
    bot_token: $TELEGRAM_BOT_TOKEN
    allowed_users: []               # 数値のユーザー ID(@ユーザー名は不可)、空 = 全員許可

    # オプション: チャネル/ユーザーごとのセッション設定
    session:
      assistant_id: mobile_agent
      context:
        thinking_enabled: false
      users:
        "123456789":
          assistant_id: vip_agent
          config:
            recursion_limit: 150
          context:
            thinking_enabled: true
            subagent_enabled: true

  wechat:
    enabled: false
    bot_token: $WECHAT_BOT_TOKEN
    ilink_bot_id: $WECHAT_ILINK_BOT_ID
    qrcode_login_enabled: true      # オプション:bot_tokenがない場合に初回のQRブートストラップを許可
    allowed_users: []               # 空 = 全員許可
    polling_timeout: 35
    state_dir: ./.deer-flow/wechat/state
    max_inbound_image_bytes: 20971520
    max_outbound_image_bytes: 20971520
    max_inbound_file_bytes: 52428800
    max_outbound_file_bytes: 52428800

  dingtalk:
    enabled: true
    client_id: $DINGTALK_CLIENT_ID             # DingTalk Open PlatformのClientId
    client_secret: $DINGTALK_CLIENT_SECRET     # DingTalk Open PlatformのClientSecret
    allowed_users: []                          # 空 = 全員許可
    card_template_id: ""                       # オプション:ストリーミングタイプライター効果用のAIカードテンプレートID
対応するAPIキーを.envファイルに設定します:
# Telegram
TELEGRAM_BOT_TOKEN=123456789:ABCdefGHIjklMNOpqrSTUvwxYZ

# Slack
SLACK_BOT_TOKEN=xoxb-...
SLACK_APP_TOKEN=xapp-...

# Feishu / Lark
FEISHU_APP_ID=cli_xxxx
FEISHU_APP_SECRET=your_app_secret

# WeChat iLink
WECHAT_BOT_TOKEN=your_ilink_bot_token
WECHAT_ILINK_BOT_ID=your_ilink_bot_id

# WeCom
WECOM_BOT_ID=your_bot_id
WECOM_BOT_SECRET=your_bot_secret

# DingTalk
DINGTALK_CLIENT_ID=your_client_id
DINGTALK_CLIENT_SECRET=your_client_secret
Telegramのセットアップ
- @BotFatherとチャットし、
/newbotを送信してHTTP APIトークンをコピーします。 .envにTELEGRAM_BOT_TOKENを設定し、config.yamlでチャネルを有効にします。
Slackのセットアップ
- api.slack.com/appsでSlackアプリを作成 → 新規アプリ作成 → 最初から作成。
- OAuth & Permissionsで、Botトークンスコープを追加:
app_mentions:read、chat:write、im:history、im:read、im:write、files:write。 - Socket Modeを有効化 →
connections:writeスコープのApp-Levelトークン(xapp-…)を生成。 - Event Subscriptionsで、ボットイベントを購読:
app_mention、message.im。 .envにSLACK_BOT_TOKENとSLACK_APP_TOKENを設定し、config.yamlでチャネルを有効にします。
Feishu / Larkのセットアップ
- Feishu Open Platformでアプリを作成 → ボット機能を有効化。
- 権限を追加:
im:message、im:message.p2p_msg:readonly、im:resource。 - イベントで
im.message.receive_v1を購読し、ロングコネクションモードを選択。 - App IDとApp Secretをコピー。
.envにFEISHU_APP_IDとFEISHU_APP_SECRETを設定し、config.yamlでチャネルを有効にします。
WeChatのセットアップ
config.yamlでwechatチャネルを有効にします。.envにWECHAT_BOT_TOKENを設定するか、初回のQRブートストラップのためにqrcode_login_enabled: trueを設定します。bot_tokenがなくQRブートストラップが有効な場合は、バックエンドログでiLinkが返したQRコンテンツを監視し、バインドフローを完了します。- QRフローが成功した後、DeerFlowは取得したトークンを
state_dirに永続化し、以降の再起動で再利用します。 - Docker Composeデプロイでは、
state_dirを永続ボリュームに置き、get_updates_bufカーソルと保存済みの認証ステートが再起動後も保持されるようにしてください。
WeComのセットアップ
- WeCom AI Botプラットフォームでボットを作成し、
bot_idとbot_secretを取得します。 config.yamlでchannels.wecomを有効にし、bot_id/bot_secretを入力します。.envにWECOM_BOT_IDとWECOM_BOT_SECRETを設定します。- バックエンドの依存関係に
wecom-aibot-python-sdkが含まれていることを確認してください。このチャネルはWebSocketロングコネクションを使用し、パブリックなコールバックURLは不要です。 - 現在の統合では、受信テキスト、画像、ファイルメッセージをサポートしています。エージェントが生成した最終的な画像/ファイルもWeComの会話に送り返されます。
DingTalkのセットアップ
- DingTalk Open Platformでアプリを作成し、ロボット機能を有効化します。
- ロボット設定ページでメッセージ受信モードをStreamモードに設定します。
Client IDとClient Secretをコピー。.envにDINGTALK_CLIENT_IDとDINGTALK_CLIENT_SECRETを設定し、config.yamlでチャネルを有効にします。- (オプション) ストリーミングAIカード返信(タイプライター効果)を有効にするには、DingTalkカードプラットフォームでAIカードテンプレートを作成し、
config.yamlのcard_template_idにテンプレートIDを設定します。Card.Streaming.WriteおよびCard.Instance.Write権限の申請も必要です。
コマンド
チャネル接続後、チャットから直接DeerFlowと対話できます:
| コマンド | 説明 |
|---|---|
/new |
新しい会話を開始 |
/status |
現在のスレッド情報を表示 |
/models |
利用可能なモデルを一覧表示 |
/memory |
メモリを表示 |
/help |
ヘルプを表示 |
コマンドプレフィックスのないメッセージは通常のチャットとして扱われ、DeerFlowがスレッドを作成して会話形式で応答します。
LangSmithトレーシング
DeerFlowにはLangSmithによる可観測性が組み込まれています。有効にすると、すべてのLLM呼び出し、エージェント実行、ツール実行がトレースされ、LangSmithダッシュボードで確認できます。
.envファイルに以下を追加します:
LANGSMITH_TRACING=true
LANGSMITH_ENDPOINT=https://api.smith.langchain.com
LANGSMITH_API_KEY=lsv2_pt_xxxxxxxxxxxxxxxx
LANGSMITH_PROJECT=xxx
Langfuseトレーシング
DeerFlowは、LangChain互換の実行に対してLangfuseによる可観測性もサポートしています。
.envファイルに以下を追加します:
LANGFUSE_TRACING=true
LANGFUSE_PUBLIC_KEY=pk-lf-xxxxxxxxxxxxxxxx
LANGFUSE_SECRET_KEY=sk-lf-xxxxxxxxxxxxxxxx
LANGFUSE_BASE_URL=https://cloud.langfuse.com
セルフホストのLangfuseインスタンスを使用している場合は、LANGFUSE_BASE_URLをデプロイ先のURLに設定します。
トレース関連付けフィールド。 各エージェント実行には、Langfuseの予約済みトレース属性が付与されるため、SessionsページとUsersページが自動的に表示されます:
session_id= LangGraphのthread_id——同一会話のすべてのトレースをグループ化しますuser_id=get_effective_user_id()から取得した有効なユーザー(認証なしモードではdefaultにフォールバック)trace_name= assistant id(デフォルトはlead-agent)tags=[env:<DEER_FLOW_ENV>, model:<model_name>](未設定の場合は省略)metadata.deerflow_trace_id= DeerFlowのリクエスト関連付けid。常に同じリクエストが返すX-Trace-Idレスポンスヘッダーと一致します(logging.enhance.enabledはこのidをログに出力するかどうかのみを制御します)
これらは、gatewayパス(runtime/runs/worker.py::run_agent)と埋め込みパス(client.py::DeerFlowClient.stream)の両方で、グラフ呼び出しのルートでRunnableConfig.metadataに注入されるため、LangChain互換の任意のcallbackから読み取れます。DEER_FLOW_ENV(またはENVIRONMENT)を設定すると、デプロイ環境ごとにトレースにタグを付けられます。
両方のプロバイダーを使用する
LangSmithとLangfuseの両方を有効にすると、DeerFlowは両方のトレーシングcallbackを取り付け、同じモデルアクティビティを両方のシステムに報告します。
あるプロバイダーが明示的に有効化されているにもかかわらず必要な認証情報が欠けている場合、またはそのcallbackの初期化に失敗した場合、DeerFlowはモデル作成時のトレーシング初期化中に早期に失敗(fail fast)し、エラーメッセージには失敗の原因となったプロバイダー名が示されます。
Dockerデプロイでは、トレーシングはデフォルトで無効です。.envでLANGSMITH_TRACING=trueとLANGSMITH_API_KEYを設定して有効にします。
Deep Researchからスーパーエージェントハーネスへ
DeerFlowはDeep Researchフレームワークとして始まり、コミュニティがそれを大きく発展させました。リリース以来、開発者たちはリサーチを超えて活用してきました:データパイプラインの構築、スライドデッキの生成、ダッシュボードの立ち上げ、コンテンツワークフローの自動化。私たちが予想もしなかったことです。
これは重要なことを示していました:DeerFlowは単なるリサーチツールではなかったのです。それはハーネス——エージェントが実際に仕事をこなすためのインフラを提供するランタイムでした。
そこで、ゼロから再構築しました。
DeerFlow 2.0は、もはやつなぎ合わせるフレームワークではありません。バッテリー同梱、完全に拡張可能なスーパーエージェントハーネスです。LangGraphとLangChainの上に構築され、エージェントが必要とするすべてを標準搭載しています:ファイルシステム、メモリ、スキル、サンドボックス実行、そして複雑なマルチステップタスクのためのプランニングとサブエージェントの生成機能。
そのまま使うもよし。分解して自分のものにするもよし。
コア機能
スキルとツール
スキルこそが、DeerFlowをほぼ何でもできるものにしています。
標準的なエージェントスキルは構造化された機能モジュールです——ワークフロー、ベストプラクティス、サポートリソースへの参照を定義するMarkdownファイルです。DeerFlowにはリサーチ、レポート生成、スライド作成、Webページ、画像・動画生成などの組み込みスキルが付属しています。しかし、真の力は拡張性にあります:独自のスキルを追加し、組み込みスキルを置き換え、複合ワークフローに組み合わせることができます。
スキルはプログレッシブに読み込まれます——タスクが必要とする時にのみ、一度にすべてではありません。これによりコンテキストウィンドウを軽量に保ち、トークンに敏感なモデルでもDeerFlowがうまく動作します。
Gateway経由で.skillアーカイブをインストールする際、DeerFlowはversion、author、compatibilityなどの標準的なオプショナルフロントマターメタデータを受け入れ、有効な外部スキルを拒否しません。
ツールも同じ哲学に従います。DeerFlowにはコアツールセット——Web検索、Webフェッチ、ファイル操作、bash実行——が付属し、MCPサーバーやPython関数によるカスタムツールをサポートしています。何でも入れ替え可能、何でも追加可能です。
Gatewayが生成するフォローアップ提案は、プレーン文字列のモデル出力とブロック/リスト形式のリッチコンテンツの両方をJSON配列レスポンスの解析前に正規化するため、プロバイダー固有のコンテンツラッパーが提案をサイレントにドロップすることはありません。
# サンドボックスコンテナ内のパス
/mnt/skills/public
├── research/SKILL.md
├── report-generation/SKILL.md
├── slide-creation/SKILL.md
├── web-page/SKILL.md
└── image-generation/SKILL.md

/mnt/skills/custom
└── your-custom-skill/SKILL.md      ← あなたのカスタムスキル
Claude Code連携
claude-to-deerflowスキルを使えば、Claude Codeから直接、実行中のDeerFlowインスタンスと対話できます。リサーチタスクの送信、ステータスの確認、スレッドの管理——すべてターミナルから離れずに実行できます。
スキルのインストール:
npx skills add https://github.com/bytedance/deer-flow --skill claude-to-deerflow
DeerFlowが実行中であることを確認し(デフォルトはhttp://localhost:2026)、Claude Codeで/claude-to-deerflowコマンドを使用します。
できること:
- DeerFlowにメッセージを送信してストリーミングレスポンスを取得
- 実行モードの選択:flash(高速)、standard、pro(プランニング)、ultra(サブエージェント)
- DeerFlowのヘルスチェック、モデル/スキル/エージェントの一覧表示
- スレッドと会話履歴の管理
- 分析用ファイルのアップロード
環境変数(オプション、カスタムエンドポイント用):
DEERFLOW_URL=http://localhost:2026            # 統合プロキシベースURL
DEERFLOW_GATEWAY_URL=http://localhost:2026    # Gateway API
DEERFLOW_LANGGRAPH_URL=http://localhost:2026/api/langgraph  # LangGraph API
完全なAPIリファレンスはskills/public/claude-to-deerflow/SKILL.mdをご覧ください。
セッションゴール (Session Goals)
/goal <完了条件>を使うと、現在のスレッドに1つのアクティブな完了条件を紐付けられます。このゴールはスレッドスコープのステートであり、スキルの有効化ではないため、DeerFlowが満たされたと判定するか、あなたがクリアするまでターンをまたいで有効なまま維持されます。
対応するコマンド:
/goal finish the implementation and make all tests pass
/goal              # アクティブなゴールを表示
/goal clear        # クリアする
各Gateway駆動のrunの後に、DeerFlowはnon-thinkingな評価モデルを使って、可視の会話(アシスタントのツール呼び出しと短縮されたツール結果を含む)をアクティブなゴールと照らし合わせます。ツール呼び出しが成功しただけではゴールは達成されず、アシスタントが欠けている情報や曖昧な情報を推測する必要があった場合、評価モデルはneeds_user_inputを返します。評価モデルは型付きblocker(missing_evidence、needs_user_input、run_failed、external_wait、goal_not_met_yet)と可視の証拠を返さなければなりません。DeerFlowがhidden continuationを注入するのは、直近のassistantターンが耐久性のあるチェックポイントに保存され、blockerがgoal_not_met_yetであり、評価中にスレッドが変化せず、no-progressブレーカーが発火していない場合のみです。安全上限はデフォルトで8回のhidden continuationで、同一の非進行評価が繰り返されると2回で停止します。/goal clearと、ユーザーが手書きした新規入力はすべて、キュー内のcontinuationより優先されます。ゴールが満たされると、DeerFlowは自動的にクリアし、更新されたスレッドステートを公開します。
Web UIは入力欄の上にアクティブなゴールを表示します。同じコマンドはTUIとサポート対象のIMチャネルからも利用できます。Web UIとサポート対象のIMチャネルでは、/goal <完了条件>を設定するとその条件をタスクとしてrunを開始します。ステータス確認やクリアのコマンドはゴールステートの管理のみを行います。
サブエージェント
複雑なタスクは単一のパスに収まりません。DeerFlowはそれを分解します。
リードエージェントはオンザフライでサブエージェントを生成できます——それぞれ独自のスコープ付きコンテキスト、ツール、終了条件を持ちます。サブエージェントは可能な限り並列で実行され、構造化された結果を報告し、リードエージェントがすべてを一貫した出力に統合します。
これがDeerFlowが数分から数時間かかるタスクを処理する方法です:リサーチタスクが十数のサブエージェントに展開され、それぞれが異なる角度を探索し、1つのレポート——またはWebサイト——または生成されたビジュアル付きのスライドデッキに収束します。1つのハーネス、多くの手。
サンドボックスとファイルシステム
DeerFlowは物事を語るだけではありません。自分のコンピューターを持っています。
各タスクは、完全なファイルシステムを持つ分離されたDockerコンテナ内で実行されます——スキル、ワークスペース、アップロード、出力。エージェントはファイルの読み書き・編集を行います。bashコマンドを実行し、コーディングを行います。画像を表示します。すべてサンドボックス化され、すべて監査可能で、セッション間の汚染はゼロです。
これが、ツールアクセスのあるチャットボットと、実際の実行環境を持つエージェントの違いです。
# サンドボックスコンテナ内のパス
/mnt/user-data/
├── uploads/          ← あなたのファイル
├── workspace/        ← エージェントの作業ディレクトリ
└── outputs/          ← 最終成果物
コンテキストエンジニアリング
分離されたサブエージェントコンテキスト:各サブエージェントは独自の分離されたコンテキストで実行されます。これにより、サブエージェントはメインエージェントや他のサブエージェントのコンテキストを見ることができません。これは、サブエージェントが目の前のタスクに集中し、メインエージェントや他のサブエージェントのコンテキストに気を取られないようにするために重要です。
要約化:セッション内で、DeerFlowはコンテキストを積極的に管理します——完了したサブタスクの要約、中間結果のファイルシステムへのオフロード、もはや直接関係のないものの圧縮。これにより、コンテキストウィンドウを超えることなく、長いマルチステップタスク全体を通じてシャープさを維持します。
長期メモリ
ほとんどのエージェントは、会話が終わるとすべてを忘れます。DeerFlowは記憶します。
セッションをまたいで、DeerFlowはあなたのプロフィール、好み、蓄積された知識の永続的なメモリを構築します。使えば使うほど、あなたのことをよく知るようになります——あなたの文体、技術スタック、繰り返されるワークフロー。メモリはローカルに保存され、あなたの管理下にあります。
メモリ更新は適用時に重複するファクトエントリをスキップするようになり、繰り返される好みやコンテキストがセッションをまたいで際限なく蓄積されることはありません。
推奨モデル
DeerFlowはモデルに依存しません——OpenAI互換APIを実装する任意のLLMで動作します。とはいえ、以下をサポートするモデルで最高のパフォーマンスを発揮します:
- 長いコンテキストウィンドウ(10万トークン以上):深いリサーチとマルチステップタスク向け
- 推論能力:適応的なプランニングと複雑な分解向け
- マルチモーダル入力:画像理解と動画理解向け
- 強力なツール使用:信頼性の高いファンクションコーリングと構造化された出力向け
組み込みPythonクライアント
DeerFlowは、完全なHTTPサービスを実行せずに組み込みPythonライブラリとして使用できます。DeerFlowClientは、すべてのエージェントとGateway機能へのプロセス内直接アクセスを提供し、HTTP Gateway APIと同じレスポンススキーマを返します。HTTP Gatewayは、LangGraphスレッド自体が削除された後にDeerFlow管理下のローカルスレッドデータを削除するためのDELETE /api/threads/{thread_id}も公開しています:
from deerflow.client import DeerFlowClient

client = DeerFlowClient()

# チャット
response = client.chat("Analyze this paper for me", thread_id="my-thread")

# ストリーミング(LangGraph SSEプロトコル:values、messages-tuple、end)
for event in client.stream("hello"):
    if event.type == "messages-tuple" and event.data.get("type") == "ai":
        print(event.data["content"])

# 設定&管理 — Gateway準拠のdictを返す
models = client.list_models()        # {"models": [...]}
skills = client.list_skills()        # {"skills": [...]}
client.update_skill("web-search", enabled=True)
client.upload_files("thread-1", ["./report.pdf"])  # {"success": True, "files": [...]}
client.set_goal("thread-1", "finish the implementation and make all tests pass")
client.get_goal("thread-1")       # {"goal": {...}} or {"goal": None}
client.clear_goal("thread-1")
すべてのdict返却メソッドはCIでGateway Pydanticレスポンスモデルに対して検証されており(TestGatewayConformance)、組み込みクライアントがHTTP APIスキーマと同期していることを保証します。完全なAPIドキュメントはbackend/packages/harness/deerflow/client.pyをご覧ください。
プロジェクト (Projects)
プロジェクトは、関連する会話を共有の名前・指示・ドキュメントシェルフのもとにまとめます。
会話は作成時(プロジェクトを選択した場合)に、または後から移動メニューを使ってプロジェクトに参加します。実行がメンバーシップを変更することはありません。メッセージを送信しても、会話の割り当てや再割り当ては行われません。会話をプロジェクトから移動すると、再度明示的に移動されるまで未割り当ての状態が保たれます。
会話を移動すると、古いメタデータリクエストがまだ処理中の場合でも、ヘッダーの所属表示とプロジェクトリストが更新されます。
プロジェクトには最新のデータベーステーブルとカラムが必要です。古い 0018 ベースのロールアウトで 0019_thread_incarnations にスタンプされたデータベースは、プロジェクトのスキーマが不足している場合、起動時に拒否されます。そのデータベースに対してこのビルドを起動する前に、オフラインデータベース復旧手順 に従ってください。
プロジェクト指示 (Project instructions)
各プロジェクトは、プロジェクト内のすべての会話に適用される背景・規約・制約を、自由形式の指示として保存します。プロジェクトページの Instructions タブで編集でき、バイト数がリアルタイムで表示されます。メンバースレッドで実行が開始されると、Gateway はプロジェクトの現在の状態を一度だけ固定(pin)し、その実行専用の有界でリクエストスコープの <project> ブロックとして指示をレンダリングします。このブロックがシステムプロンプトや永続化された履歴に入ることはなく、新しい実行ごとに最新の保存済み指示が参照されます。指示の長さは projects.instructions_max_bytes UTF-8 バイト(デフォルト 8192、範囲 256–262144)に制限され、マルチバイト文字はその UTF-8 バイト長として数えられます。サイズ超過の指示は書き込み時に 422 で拒否され、黙って切り詰められることはありません。
ドキュメントシェルフ (Document shelf)
各プロジェクトには、プロジェクト全体で共有するファイルのためのドキュメントシェルフがあり、プロジェクトページの Documents セクションから管理します:
- アップロード:ファイルをアップロードします(ボタンまたはドラッグ&ドロップ、1 リクエストにつき 1 ファイル)。シェルフのサイズ上限は
uploads.max_file_size(デフォルト 50 MiB)を再利用します。同一内容を再アップロードしても重複は作成されず、既存のエントリが返されます。 - 一覧表示:名前・サイズ・更新時刻・出自(直接アップロードか、会話から保存か)付きでエントリを一覧表示し、任意のエントリをプレビューまたはダウンロードできます。
- プロジェクトへ保存:シェルフの下にある読み取り専用の会話ファイルブラウザにメンバースレッドのアップロードと出力が一覧表示され、各エントリに「プロジェクトへ保存」アクションが用意されます。
- スレッドにアタッチ:シェルフのファイルを通常の取り込みパイプラインを通じてスレッドのアップロードにコピーし、会話から直接扱えるようにします。
メンバースレッドの実行では、固定されたスナップショットから実行ごとにレンダリングされた有界な <documents> インデックス(projects.shelf_index_max_entries と projects.shelf_index_max_bytes で上限設定)も受け取ります。エージェントは list_project_documents および read_project_document ツールでシェルフをページングし、ドキュメントを読むことができます。
アーカイブ時の読み取り動作 (Archive read semantics)
プロジェクトをアーカイブすると書き込みは凍結されますが、読み取りは維持されます。アーカイブされたプロジェクトのスレッドは引き続き実行でき、プロジェクトの指示とシェルフインデックスも受け取ります。シェルフも完全に読み取り可能で、一覧表示・プレビュー/ダウンロード・会話ファイルブラウザ・スレッドへのアタッチはすべて機能し続けます。アップロード、プロジェクトへの保存、個々のシェルフファイルのゴミ箱への移動にはアクティブなプロジェクトが必要で、ゴミ箱に入ったドキュメントをアーカイブ済みプロジェクトに復元することはできません。アーカイブ済みプロジェクトの削除は引き続き可能で、そのシェルフ全体がゴミ箱に移されます。
ゴミ箱 (Trash)
シェルフのドキュメントを削除すると、消去ではなくゴミ箱に移動されます。エントリはバイト内容と出身プロジェクトのスナップショットを projects.trash_retention_days(デフォルト 30)の間保持し、その後は保持期間のクリーンアップによって完全に消去される可能性があります。/workspace/trash ページ(プロジェクトページの Documents セクションとサイドバーの Projects 見出しからアクセス可能)には、ゴミ箱のドキュメントが出身プロジェクトと残り保持期間付きで一覧表示され、エントリごとの「復元」と「完全に削除」アクションに加え、「ゴミ箱を空にする」アクションが用意されています。これはゴミ箱内のすべてのドキュメントを保持期間の経過を待たずに即座に完全削除します。保持期間は、クリーンアップがエントリを回収するまでエントリがそこに留まれる期間の上限を定めるだけです。復元では、ドキュメントは出身プロジェクトへ戻されます。出身プロジェクトが削除済みまたはアーカイブ済みの場合は、選択したプロジェクトへ戻されます。復元先に同一内容のアクティブなファイルが既にある場合、エントリは統合されます。プロジェクトを削除すると、そのシェルフ全体が同じ操作でゴミ箱に移されます。
スケジュールタスク (Scheduled Tasks)
DeerFlowには現在、ワークスペース内でファーストクラスのスケジュールタスクMVPが組み込まれています。
現在のMVPの機能:
/workspace/scheduled-tasksでタスクを管理- 各スケジュールタスクがスレッドを再利用するか、実行ごとに新しいスレッドを作成するかを選択可能
once、cron、intervalのスケジュールをサポート- バックグラウンドのスケジュール実行を非対話型のDeerFlow runとして実行(
ask_clarificationはここでは公開されません) - 再利用された同じスレッド上でアクティブなrunと衝突する期限到来のcron実行に対して
skipオーバーラップ挙動を使用 - タスクの一時停止、再開、トリガー、履歴確認、削除
- スケジュールされた作業を通常のDeerFlow runライフサイクルを通じて実行
現在のMVPの制限:
- テキストのみの通知ジョブはありません
- チャネルやGitHubのディスパッチターゲットはありません
config.yaml -> scheduler.enabledでバックグラウンドポーリングを有効にします。手動トリガーは同じスケジュールタスクリソースと実行パスを使用します。
ライフサイクル、安全上限、停止条件
- タスクページとREST API(
POST/PATCH /api/scheduled-tasks)は、実行ごとの目標(goal_objective)、安全上限(max_runs、end_at)、停止条件(stop_condition)を受け付けます。PATCHでnullを送ると、この4項目のいずれかを消去できます。UTCオフセットのないend_atはタスクのタイムゾーンの現地時刻として扱われます。 - 停止条件は「〜になったら止める」というユーザーのルールです。専用のフィールド(マイグレーション
0031)に保存され、タスクの指示には含まれません。DeerFlowは実行の開始時にのみ、その実行のメッセージへ停止条件を追加し、条件が満たされたらstop_scheduled_taskを呼ぶよう指示します。scheduler.tool_enabledが有効な間は、タスクが会話とタスクページのどちらで作成されたかにかかわらず、すべてのスケジュール実行が自分のスケジュールを一時停止できます。無効な場合、実行は条件を満たしたことを報告するだけです。 - タスクページで作成した目標付きタスクも、会話で作成したタスクと同様に目標が評価され、その実行には保存済みのメモと前回の実行への参照も渡されます。
- 再開すると次回の実行は現在時刻から計算されるため、長く一時停止していても取り戻しの実行は発生しません。時刻を過ぎた単発タスクは
422 once_time_passedを返し、新しい時刻の設定が必要です。有効なタスクを再開しても何も変わりません。終了したタスクを一時停止すると409 task_finishedを返します。 max_runsはタスクの全期間を通じた自動実行の合計で、試行実行は数えません。上限を使い切ったタスクを再び有効にする操作(再開、または終了したタスクのスケジュールを再設定するPATCH)は、使い切った上限を同じリクエストで更新しない限り409 limits_exhaustedを返します。実行回数を使い切った場合はmax_runsを引き上げるかnullで外し、終了時刻を過ぎた場合はend_atを後ろにずらすかnullで外します(end_atを延ばすだけでは、回数を使い切ったタスクは再開できません)。そのためにPOST /api/scheduled-tasks/{task_id}/resumeは省略可能な{"max_runs": …, "end_at": …}ボディを受け付けます(nullで上限を外します)。終了したタスクの上限だけを変えるPATCHは値を保存し、タスクは終了したままです。- 目標を確認できなかった場合(評価器の失敗、または確認中に会話が変わった場合)は、3回連続未達成による自動一時停止に数えられず、カウントもリセットされません。目標・指示・停止条件の変更やメモの追加でカウントは新しく始まり、再開ではそのまま保たれます。
- このGatewayプロセスのスケジューラーが動いていない間、タスクの作成(複製を含む)は
409 scheduler_not_runningを返します。GET /api/featuresはscheduled_tasks.available、running、tool_enabled、min_interval_secondsを返します。 /api/scheduled-tasks*のエラーは{"detail": {"code", "message", "params"}}の形式です。backend/docs/API.mdとcontracts/scheduled_task_errors_contract.jsonを参照してください。- 実行枠はタスクの所有者間で公平に分配されます。1人の所有者が同時に起動中または実行中にできるスケジュール実行は最大
scheduler.max_concurrent_runs_per_user件です(既定値は2で、max_concurrent_runsを超えません。0にすると所有者ごとの上限は無効になります)。待機キューは所有者ごとに順番に取り出されるため、1人に溜まった実行が他の人の実行を妨げることはありません。scheduler.queue_timeout_secondsを超えて待った実行はスキップされ、履歴には空き枠を長く待ちすぎたと表示されます。 channel_connections.enabled: trueのとき、スケジュールタスクの更新は、プロアクティブ送信に対応したアプリ(現在はWeComのみ)で接続済みの所有者のIMアカウントに送られます。設定画面では、アプリごとに更新が送られるかどうかが表示されます。1回の実行で送られるメッセージは最大1件(実行の完了・失敗・目標未達成、自動一時停止、エージェントによる一時停止、タスクの終了)で、結果を記録するのと同じトランザクションでキューに入るため、障害からの復旧後も1回だけ通知されます。メッセージは単体で読める内容で、Web画面の表示言語(未設定ならchannel_connections.notification_locale)で書かれ、IDやリンクは含みません。単なる手動の試し実行と中断された実行は通知されません。
会話からスケジュールを作成する
scheduler.enabled: true と scheduler.tool_enabled: true を設定して Gateway を再起動すると、権限のある対話ターンで schedule_task を使い、タスクの作成・変更・一覧・一時停止・再開・削除、試運転の開始、メモの保存ができます。例:「平日の毎朝 9 時に release-checklist.md を確認して、未チェックの項目を教えて。全部チェックされたら止めて。」Web アプリでは、結果がスケジュール・停止条件・ボタンを備えたライブカードとして表示され、エージェントは 1〜2 文で返答します。IM など Web 以外のターンでは、スケジュール、次回の実行、停止条件を文章で説明します。
- 会話が管理できるタスク。 その会話で作成したタスクに加え、実行用の会話(スケジュール実行が結果を投稿した会話)では、その実行が属するタスクも管理できます。そこで「これを止めて」「10 時に変えて」と頼めます。これはあなたが送るメッセージにのみ適用され、スケジュール実行そのものは
stop_scheduled_taskで自分のスケジュールを一時停止することしかできません。 - 変更してもタスクは同じ。 時刻、指示、目標、停止条件、安全上限の変更は同じタスクへの
updateなので、タスク ID と実行履歴は保たれます。resumeは一時停止中または終了済みのタスクを再開し、取りこぼした実行の追い上げはしません。上限を使い切っている場合、エージェントは使い切った方の上限をどうするか(max_runsを増やすか外す、end_atを延ばすか外す)を確認し、それを再開と一緒に送ります。 - タイムゾーン。 あなたが指定したタイムゾーンが優先されます。指定がなければ、新しいタスクには Web アプリが各メッセージと一緒に送るブラウザのタイムゾーン(
context.client_timezone、この用途にのみ使用)が使われ、結果にどのゾーンを使ったかが示されます。間隔実行と UTC オフセット付きの単発時刻にはタイムゾーンは不要です。cron やオフセットなしの単発のローカル時刻でゾーンが分からない場合(IM など)は、エージェントが確認します。変更時は保存済みのゾーンを使い、ブラウザのゾーンで既存タスクが変わることはありません。 - 結果の表示先。 各実行は「{タスク名} · {現地時刻}」という題名の新しい会話に結果を投稿します。タスクが元の会話で実行される場合はその会話に投稿します。スケジュールがエージェントによって一時停止されたとき、自動で一時停止されたとき、または終了したときは、元の会話のその時点の位置に 1 行の通知が表示され、その実行またはタスクへのリンクが付きます。それ以外に元の会話へ投稿されるものはありません。タスクを削除してもこの行は残ります。実行用の会話では、タスクの指示が実行ヘッダーの下に折りたたまれた「タスクの指示」ブロックとして表示されます。
- 言語。 エージェントはタイトル、指示、停止条件をあなたの言語で書き、スケジュール実行は指示の言語で返答します。
- 試運転。 「Run it now」や「先跑一次吧」のように直接頼んでください。カードの Run once now ボタンでも同じです。単なる「yes」、タスクへの言及、引用や条件付きの依頼では有料の実行は始まりません。試運転は
max_runsに数えられません。
ターミナルワークベンチ (TUI)
deerflowは、シェルに暮らす人々のためのターミナルネイティブなワークベンチです。組み込みでDeerFlowClient上で実行され、Gateway、フロントエンド、nginx、Dockerは不要ですが、DeerFlowの他の部分と同じconfig.yaml、checkpointer、スキル、メモリ、MCP、サンドボックス設定を尊重します。

uv pip install 'deerflow-harness[tui]'        # オプションの'textual'依存関係

deerflow                                      # ターミナルUIを起動(TTYが必要)
deerflow --continue                           # 直近のスレッドを再開
deerflow --resume THREAD                      # IDでスレッドを再開
deerflow --print "summarize this repo"        # ヘッドレスでstdoutにワンショットの回答を出力
deerflow --json  "hello"                       # ヘッドレスで改行区切りのStreamEventを出力
ストリーミング文字起こし(Markdownでレンダリングされた回答)、コンパクトなツールアクティビティカード、/スラッシュコマンドパレット、/goalゴール管理、/modelと/threadsピッカー、入力履歴、Esc / Ctrl+C割り込みを備えた、キーボード駆動のチャット画面。TUIで開いたセッションはWeb UIのサイドバーにも表示されます。ローカルのデフォルトユーザーの下で共有スレッドストアに書き込むため、Gatewayを実行せずにターミナルとウェブが同期します。
完全なガイドはbackend/docs/TUI.mdをご覧ください。
ドキュメント
- コントリビュートガイド - 開発環境のセットアップとワークフロー
- 設定ガイド - セットアップと設定の手順
- アーキテクチャ概要 - 技術的なアーキテクチャの詳細
- バックエンドアーキテクチャ - バックエンドアーキテクチャとAPIリファレンス
⚠️ セキュリティに関する注意
不適切なデプロイはセキュリティリスクを引き起こす可能性があります
DeerFlowはシステムコマンドの実行、リソース操作、ビジネスロジックの呼び出しなどの重要な高権限機能を備えており、デフォルトではローカルの信頼できる環境(127.0.0.1のループバックアクセスのみ)にデプロイされる設計になっています。信頼できないLAN、公開クラウドサーバー、または複数のエンドポイントからアクセス可能なネットワーク環境にエージェントをデプロイし、厳格なセキュリティ対策を講じない場合、以下のようなセキュリティリスクが生じる可能性があります:
- 不正な違法呼び出し:エージェントの機能が権限のない第三者や悪意のあるインターネットスキャナーに発見され、システムコマンドやファイル読み書きなどの高リスク操作を実行する不正な一括リクエストが引き起こされ、重大なセキュリティ上の問題が発生する可能性があります。
- コンプライアンスおよび法的リスク:エージェントがサイバー攻撃やデータ窃取などの違法行為に不正使用された場合、法的責任やコンプライアンス上のリスクが生じる可能性があります。
セキュリティ推奨事項
注意:DeerFlowはローカルの信頼できるネットワーク環境にデプロイすることを強く推奨します。 クロスデバイス・クロスネットワークのデプロイが必要な場合は、以下のような厳格なセキュリティ対策を実装する必要があります:
- IPホワイトリストの設定:
iptablesを使用するか、ハードウェアファイアウォール / ACL機能付きスイッチをデプロイしてIPホワイトリストルールを設定し、他のすべてのIPアドレスからのアクセスを拒否します。 - 前置認証:リバースプロキシ(nginxなど)を設定し、強力な前置認証を有効化して、認証なしのアクセスをブロックします。
- ネットワーク分離:可能であれば、エージェントと信頼できるデバイスを同一の専用VLANに配置し、他のネットワークデバイスから隔離します。
- アップデートを継続的に確認:DeerFlowのセキュリティ機能のアップデートを継続的にフォローしてください。
コントリビュート
コントリビューションを歓迎します!開発環境のセットアップ、ワークフロー、ガイドラインについてはCONTRIBUTING.mdをご覧ください。
回帰テストのカバレッジには、backend/tests/でのDockerサンドボックスモード検出とプロビジョナーkubeconfig-pathハンドリングテストが含まれます。
ライセンス
このプロジェクトはオープンソースであり、MITライセンスの下で提供されています。
謝辞
DeerFlowはオープンソースコミュニティの素晴らしい成果の上に構築されています。DeerFlowを可能にしてくれたすべてのプロジェクトとコントリビューターに深く感謝いたします。まさに、巨人の肩の上に立っています。
以下のプロジェクトの貴重な貢献に心からの感謝を申し上げます:
- LangChain:その優れたフレームワークがLLMのインタラクションとチェーンを支え、シームレスな統合と機能を実現しています。
- LangGraph:マルチエージェントオーケストレーションへの革新的なアプローチが、DeerFlowの洗練されたワークフローの実現に大きく貢献しています。
これらのプロジェクトはオープンソースコラボレーションの変革的な力を体現しており、その基盤の上に構築できることを誇りに思います。
主要コントリビューター
DeerFlowのコア著者に心からの感謝を捧げます。そのビジョン、情熱、献身がこのプロジェクトに命を吹き込みました:
揺るぎないコミットメントと専門知識が、DeerFlowの成功の原動力です。この旅の先頭に立ってくださっていることを光栄に思います。