 cee54cdd49
* fix(web-fetch): stop sending .env.example placeholder keys to providers

make config and make setup copy .env.example into .env, and the template
set nine search/fetch provider keys to example values such as
JINA_API_KEY=your-jina-api-key. The default keyless Jina Reader sent
that text as a Bearer key, so every web_fetch on a fresh install failed
with 401 while make doctor reported web fetch as configured.

- .env.example comments those nine lines out, like every other credential
  in the template already is.
- provider_credentials.resolve_api_key reads a your-...-key/-token/-secret
  value as unset, so existing .env files that still hold the placeholders
  recover without editing, for every provider that resolves keys there.

* chore: leave the changelog entry to merge time

Per CONTRIBUTING.md (#8202), maintainers add changelog entries when they
merge a pull request.

* fix(web-search): route every provider key and doctor through one placeholder rule

Review follow-up for #8206:

- provider_credentials exposes is_template_placeholder(), the single
  definition of an .env.example example value. key/token/secret must be
  a whole hyphen-separated word, so a real value such as your-monkey or
  your-passkey is no longer dropped.
- Serper, Serply, Sofya, SpecStream, Unbrowse, Webz, Brave, Tencent WSA
  and You.com resolve config and environment keys through
  resolve_api_key instead of private strip-and-send copies, so an old
  .env that still holds the template value no longer sends it.
- make doctor asks the same predicate: a placeholder key is reported as
  still holding the .env.example value instead of "set", and a literal
  placeholder in config.yaml falls back to the environment key as the
  runtime does.
- A census test keeps credential environment reads under community/
  wrapped in resolve_api_key.

* fix(web-search): match shipped placeholders exactly and mirror Browserless precedence in doctor

Second review follow-up for #8206:

- is_template_placeholder() matches exactly the your-... values that
  .env.example ships instead of a pattern, so a token an operator chose
  (a self-hosted Browserless TOKEN such as your-review-team-token) is
  sent again. A test keeps the set equal to the template.
- make doctor mirrors Browserless: a configured token field is
  authoritative, blank or not, and BROWSERLESS_TOKEN is read only when
  the field is omitted. A blank or placeholder token now warns instead
  of reporting the variable, cross-checked against the client.
- The keyless Jina and You.com providers stay ok but name JINA_API_KEY
  or YDC_API_KEY when a placeholder there is ignored, and a literal
  placeholder api_key in config.yaml is named when no env key backs it.

* fix(doctor): match each web provider's key precedence; drop the dead Jina api_key from docs

Found while re-checking #8206 against every provider's runtime:

- Browserless used as web_fetch had no doctor key check; it now gets the
  same authoritative token handling as web_capture.
- InfoQuest reads only INFOQUEST_API_KEY, so doctor no longer counts an
  api_key field in its tool config as configured.
- GroundRoute needs a key for every call but had no doctor entry, so a
  missing key reported ok.
- You.com names a placeholder api_key in config that it ignores.
- The Jina web_fetch docs snippet carried api_key: $JINA_API_KEY, which
  the tool never reads. With JINA_API_KEY now commented out in
  .env.example, that line made config loading fail on a fresh install.
- The provider_credentials docstring now scopes doctor's use of the
  predicate to web provider keys, and the scripts guide no longer says
  .env.example ships live placeholder keys.
English | 中文 | 日本語 | Français | Русский | Português | 한국어

On February 28th, 2026, DeerFlow claimed the 🏆 #1 spot on GitHub Trending following the launch of version 2. Thanks a million to our incredible community — you made this happen! 💪🔥
DeerFlow (Deep Exploration and Efficient Research Flow) is an open-source super agent harness that orchestrates sub-agents, memory, and sandboxes to do almost anything — powered by extensible skills.
https://github.com/user-attachments/assets/a8bcadc4-e040-4cf2-8fda-dd768b999c18
Note
DeerFlow 2.0 is a ground-up rewrite. It shares no code with v1. If you're looking for the original Deep Research framework, it's maintained on the
1.xbranch — contributions there are still welcome. Active development has moved to 2.0.
Official Website
Learn more and see real demos on our official website. The landing-page case studies open as allowlisted, read-only showcases without requiring a sign-in.
Sister Projects
- LLM Space - Meet our secret weapon behind DeerFlow — one desktop tool to prototype agent ideas, inspect each harness step, replay failures, and benchmark performance.
Coding Plan from ByteDance Volcengine
- We strongly recommend using Doubao-Seed-2.0-Code, DeepSeek v3.2 and Kimi 2.5 to run DeerFlow
- Learn more
- 中国大陆地区的开发者请点击这里
InfoQuest
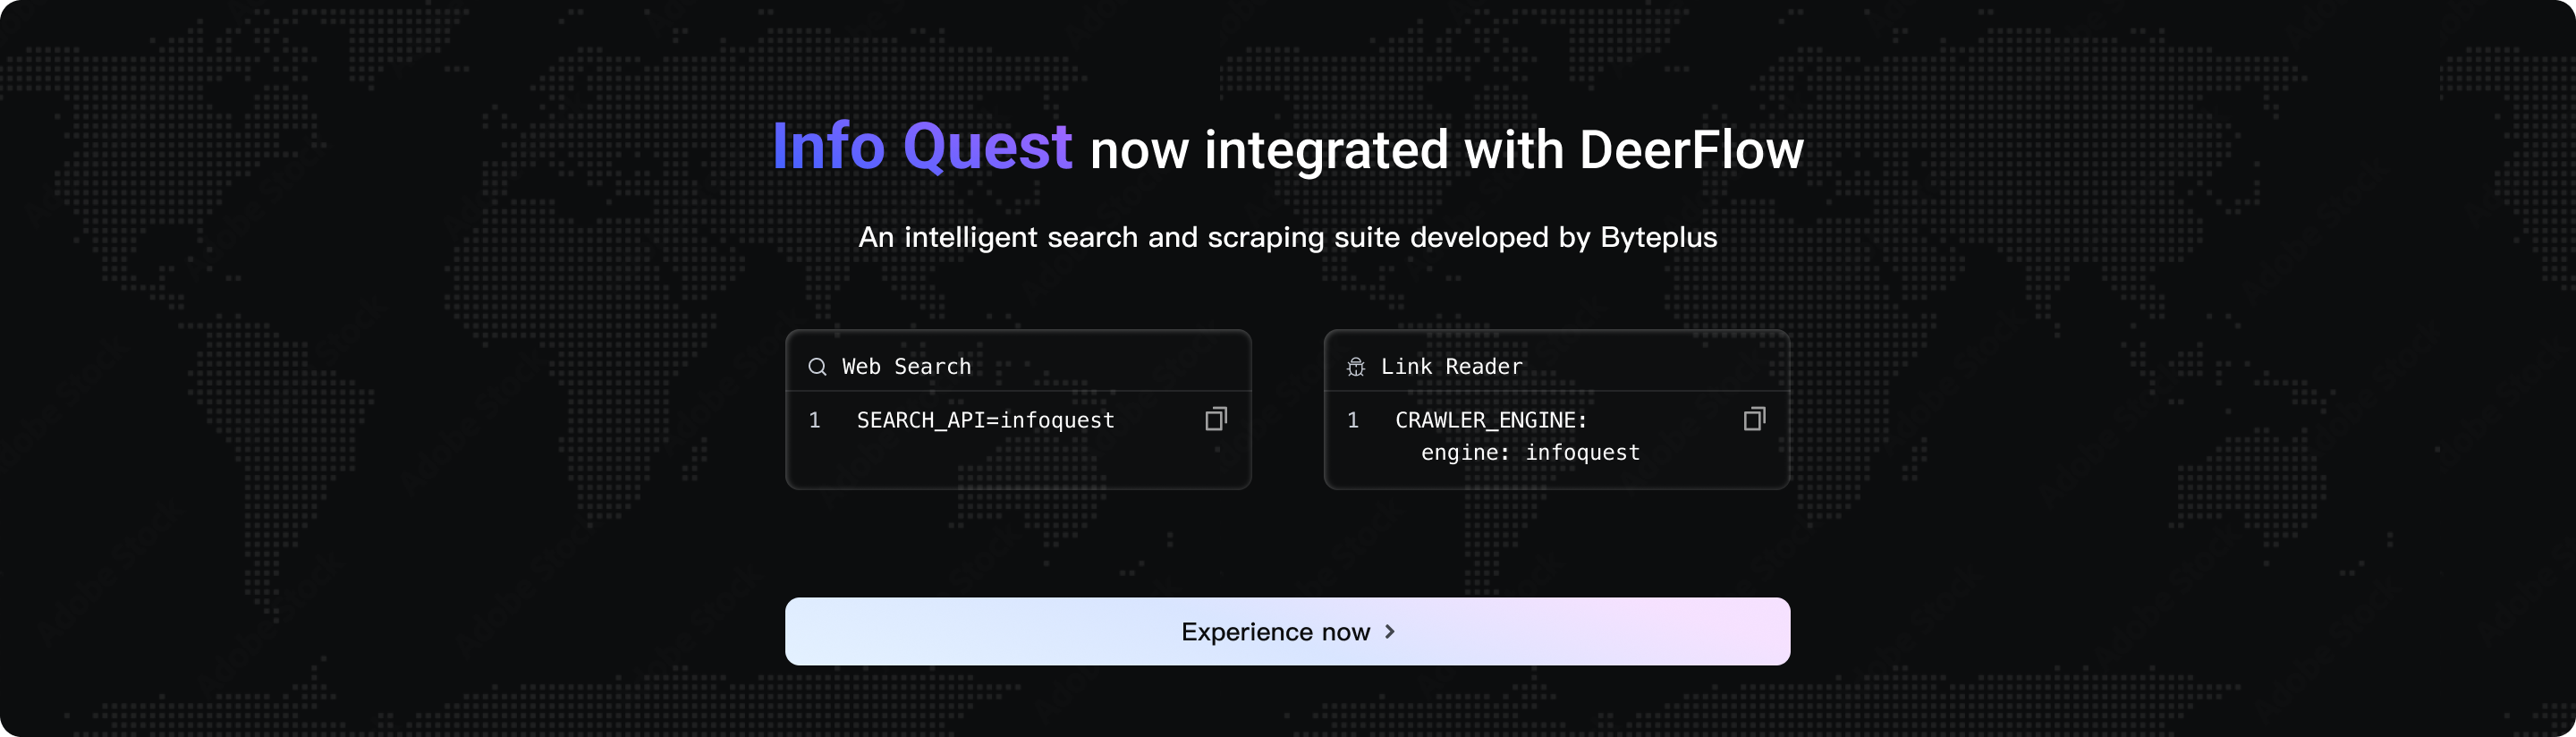
DeerFlow has newly integrated the intelligent search and crawling toolset independently developed by BytePlus — InfoQuest (supports free online experience)
One-Line Agent Setup
If you use Claude Code, Codex, Cursor, Windsurf, or another coding agent, you can hand it the setup instructions in one sentence:
Help me clone DeerFlow if needed, then bootstrap it for local development by following https://raw.githubusercontent.com/bytedance/deer-flow/main/Install.md
That prompt is intended for coding agents. It tells the agent to clone the repo if needed, choose Docker when available, and stop with the exact next command plus any missing config the user still needs to provide.
Quick Start
git clone https://github.com/bytedance/deer-flow.git
cd deer-flow
make setup          # interactive wizard: writes config.yaml and .env (about 2 minutes)
Then start DeerFlow with Docker (recommended) or run it locally:
# Docker
make docker-init    # pull the sandbox image (once, or when the image updates)
make docker-start   # start services
# Local development
make check          # verifies Node.js 22+, pnpm, uv, nginx
make install
make dev
Run make doctor after setting model credentials. It reports obvious placeholder
API keys as incomplete configuration; replace them with real keys before testing
model calls.
Open http://localhost:2026.
- All configuration options, providers and manual setup: Configuration
- Docker details, sizing, upgrades, startup modes and production deployment: Running the Application
- Running on a server or exposing it beyond localhost: read the Security Notice first
From Deep Research to Super Agent Harness
DeerFlow started as a Deep Research framework — and the community ran with it. Since launch, developers have pushed it far beyond research: building data pipelines, generating slide decks, spinning up dashboards, automating content workflows. Things we never anticipated.
That told us something important: DeerFlow wasn't just a research tool. It was a harness — a runtime that gives agents the infrastructure to actually get work done.
So we rebuilt it from scratch.
DeerFlow 2.0 is no longer a framework you wire together. It's a super agent harness — batteries included, fully extensible. Built on LangGraph and LangChain, it ships with everything an agent needs out of the box: a filesystem, memory, skills, sandbox-aware execution, and the ability to plan and spawn sub-agents for complex, multi-step tasks.
Use it as-is. Or tear it apart and make it yours.
Guides
Each guide is the full reference for its topic. Open the one you need.
| Topic | Guide |
|---|---|
Models, providers, config.yaml, environment variables |
Configuration |
| Docker, local development, upgrades, production deployment | Running the Application |
| Sandbox modes, file system, uploads and outputs | Sandbox |
| Skills, built-in tools, script workflows, Claude Code integration | Skills & Tools |
| MCP servers | MCP Server |
| Sub-agents and task delegation | Sub-Agents, Tool restrictions |
| Long-term memory | Long-Term Memory |
| Session goals, context compaction, task notes, evidence-based decisions | Context, Goals and Agent Decisions |
| Private knowledge retrieval (RAGFlow) | Private Knowledge Retrieval |
| Agentic browser control | Agentic Browser Control |
| Projects, instructions, document shelf | Projects |
| Scheduled tasks | Scheduled Tasks |
| Feishu, Slack, Telegram, Discord, DingTalk and other IM channels | IM Channels |
| File attachments, downloads and Office previews | File Previews |
| Token usage dashboard, workspace, chat archive | Workspace UI |
| Terminal workbench | Terminal Workbench (TUI) |
| Personal access tokens, stream actions, embedded Python client | API Access and Python Client |
| Trace correlation, LangSmith, Langfuse, Monocle | Tracing and Observability |
| Deployment risks, admin model, security recommendations | Security Notice |
Recommended Models
DeerFlow is model-agnostic — it works with any LLM that implements the OpenAI-compatible API. That said, it performs best with models that support:
- Long context windows (100k+ tokens) for deep research and multi-step tasks
- Reasoning capabilities for adaptive planning and complex decomposition
- Multimodal inputs for image understanding and video comprehension
- Strong tool-use for reliable function calling and structured outputs
More Documentation
- Install.md - Setup instructions written for coding agents
- Configuration Reference - Every
config.yamloption - Backend Architecture - Backend architecture and API reference
- Architecture Overview - How the services fit together
- Contributing Guide - Development environment, workflow and tests
- Changelog - Release notes
⚠️ Security Notice
DeerFlow can execute commands and read and write files. It is designed to run in a local trusted environment, and a Gateway admin account is equivalent to code execution on the host. Before you deploy it on a server or expose it to a network, read the full Security Notice and SECURITY.md.
Contributing
We welcome contributions! Please see CONTRIBUTING.md for development setup, workflow, and guidelines.
License
This project is open source and available under the MIT License.
Acknowledgments
DeerFlow is built upon the incredible work of the open-source community. We are deeply grateful to all the projects and contributors whose efforts have made DeerFlow possible. Truly, we stand on the shoulders of giants.
We would like to extend our sincere appreciation to the following projects for their invaluable contributions:
- LangChain: Their exceptional framework powers our LLM interactions and chains, enabling seamless integration and functionality.
- LangGraph: Their innovative approach to multi-agent orchestration has been instrumental in enabling DeerFlow's sophisticated workflows.
These projects exemplify the transformative power of open-source collaboration, and we are proud to build upon their foundations.
Key Contributors
A heartfelt thank you goes out to the core authors of DeerFlow, whose vision, passion, and dedication have brought this project to life:
Your unwavering commitment and expertise have been the driving force behind DeerFlow's success. We are honored to have you at the helm of this journey.